Research

Cross-stack optimization for efficient AI systems. Instead of tuning hardware and software separately, we co-design the chip, the architecture and the algorithm so that generative AI runs efficiently on the device.
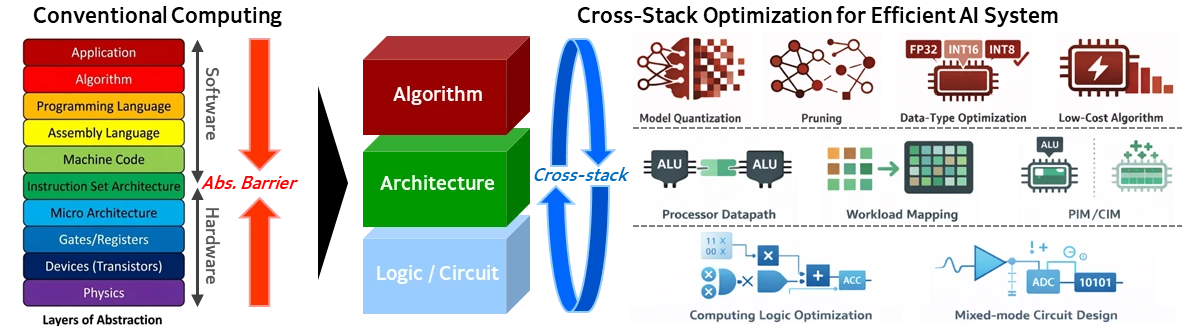
Conventional computing separates software and hardware layers with an abstraction barrier. SYMPLE Lab optimizes algorithm, architecture and logic/circuit layers together: model quantization, pruning, data-type optimization, processor datapaths, workload mapping, PIM/CIM, computing logic and mixed-mode circuit design.

Algorithm

  • Low-bit quantization
  • Rotation
  • Group quantization
  • LLM compression

Hardware-aware algorithm optimization

Lightweight AI algorithms designed around real hardware constraints.

We develop quantization algorithms that hold up across diverse generative AI models, so the same compressed model runs well on many kinds of hardware. We also design adaptive algorithms that spend computation according to how much each piece of data matters, cutting overhead while keeping accuracy high.
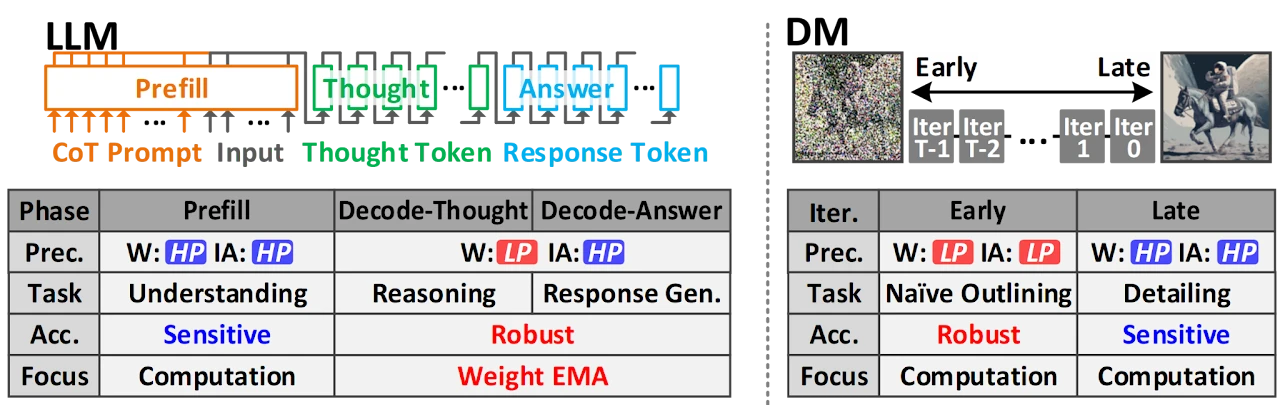
Phase-aware precision for chain-of-thought LLM inference and step-aware precision for diffusion models

Selected publications

HPCA 2026
  • Algorithm
  • Architecture
  • LLM
  • Quantization

GyRot: Leveraging Hidden Synergy between Rotation and Fine-grained Group Quantization for Low-bit LLM Inference

Sangjin Kim, Yuseon Choi, Byeongcheol Kim, Jungjun Oh, Hoi-Jun Yoo

IEEE International Symposium on High-Performance Computer Architecture, 2026

arXiv 2026
  • Algorithm
  • LLM
  • Quantization

Dual-QK: Sharp Queries and Flat Keys for Prunable 2-bit KV Caches

Sunjoo Whang, Jungjun Oh, Minsung Kim, Dongho Seo, Jisu Shin, Gregory Kielian, Hoi-Jun Yoo, Sangjin Kim

arXiv preprint, 2026, arXiv:2610.09827

MICRO 2026
  • Algorithm
  • Architecture
  • Quantization

BitDense: Dense Bit-Slice Architecture with Dynamic-Sized Group Quantization for Precision Scalable Low-Bit AI Inference

Jungjun Oh*, Sangjin Kim*, Yuseon Choi, Jingu Lee, Hoi-Jun Yoo

IEEE/ACM International Symposium on Microarchitecture, 2026 * equal contribution
Architecture

  • Processing-in-memory
  • LPDDR-PIM
  • MoE inference
  • 2.5D/3D integration

Memory-centric AI system design

AI systems built around next-generation memory.

We investigate architectures such as processing-in-memory (PIM) that merge memory and compute to get past the data-movement bottleneck. Our designs also account for 2.5D and 3D integration and packaging to raise system-level density and performance.
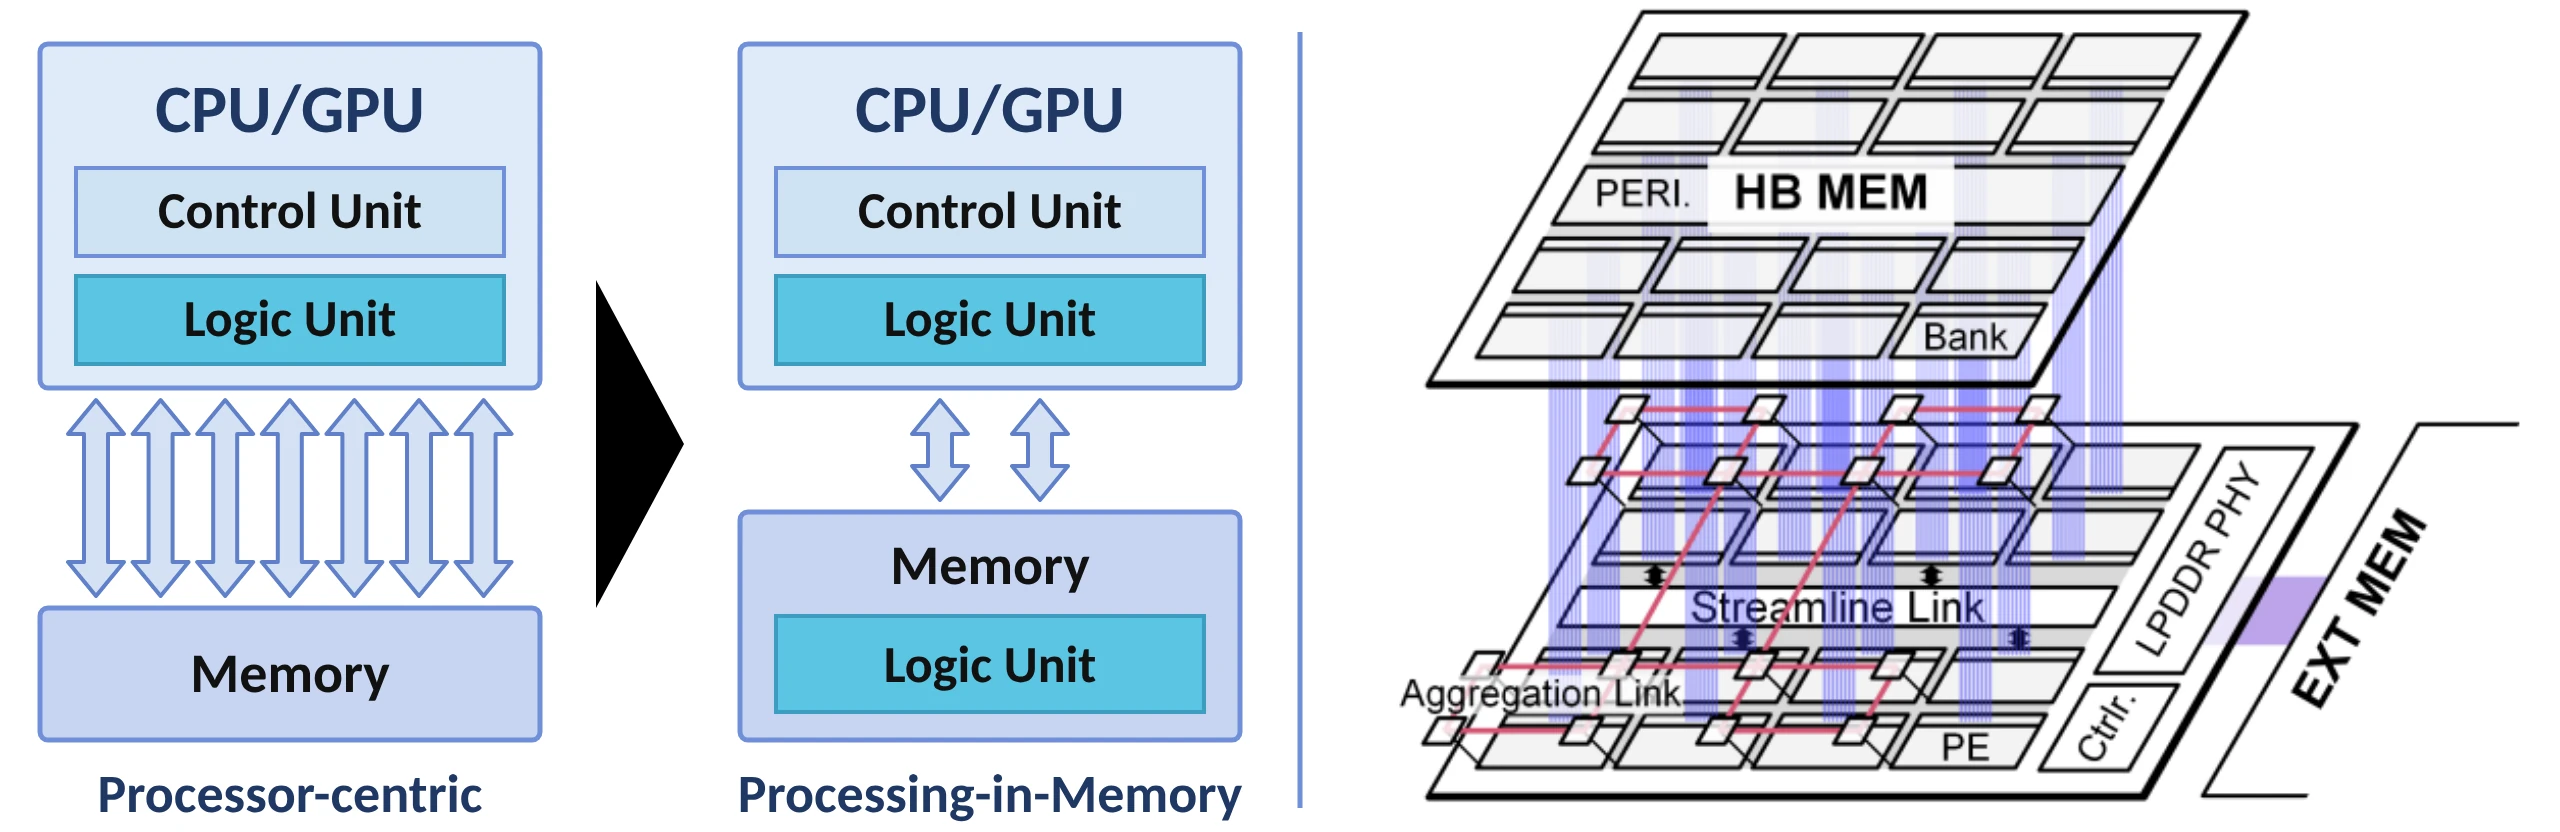
Processor-centric design versus processing-in-memory, and a hybrid-bonded memory die stacked on a logic die with PEs, streamline and aggregation links, and an LPDDR interface to external memory

Selected publications

DAC 2026
  • Architecture
  • LLM
  • Quantization

SliceMoE: Bit-Sliced Expert Caching under Miss-Rate Constraints for Efficient MoE Inference

Yuseon Choi, Sangjin Kim, Jungjun Oh, Gwangtae Park, Byeongcheol Kim, Hoi-Jun Yoo

ACM/IEEE Design Automation Conference, 2026

arXiv 2026
  • Architecture
  • Memory Architecture
  • Processing-Near-Memory
  • LLM

ELMoE-3D: Leveraging Intrinsic Elasticity of MoE for Hybrid-Bonding-Enabled Self-Speculative Decoding in On-Premises Serving

Yuseon Choi, Jingu Lee, Jungjun Oh, Sunjoo Whang, Byeongcheol Kim, Minsung Kim, Hoi-Jun Yoo, Sangjin Kim

arXiv preprint, 2026, arXiv:2604.14626

ISSCC 2026
  • Circuit
  • LLM
  • Computing-in-Memory

SMoLPU: 122.1μJ/Token Sparse MoE-based Speculative Decoding Language Processing Unit with Adaptive-Offload NPU-CIM Core

Sangwoo Ha, Jingu Lee, Youngjin Moon, Sunjoo Whang, Wooyoung Jo, Gwangtae Park, Sangjin Kim, Soyeon Um, Junha Ryu, Yurim Jo, Hoi-Jun Yoo

IEEE International Solid-State Circuits Conference, 2026

Chip

  • NPU
  • Compute-in-memory
  • Diffusion & LLM accelerators
  • Tape-out

AI accelerator SoC and chip design

Low-power, high-efficiency AI silicon for on-device platforms.

We engineer AI chips that work within the tight power, area and memory budgets of mobile and edge devices. Our work spans lightweight hardware logic, compute-in-memory macros and specialized datapaths that make real-time generative AI inference possible on the device itself.
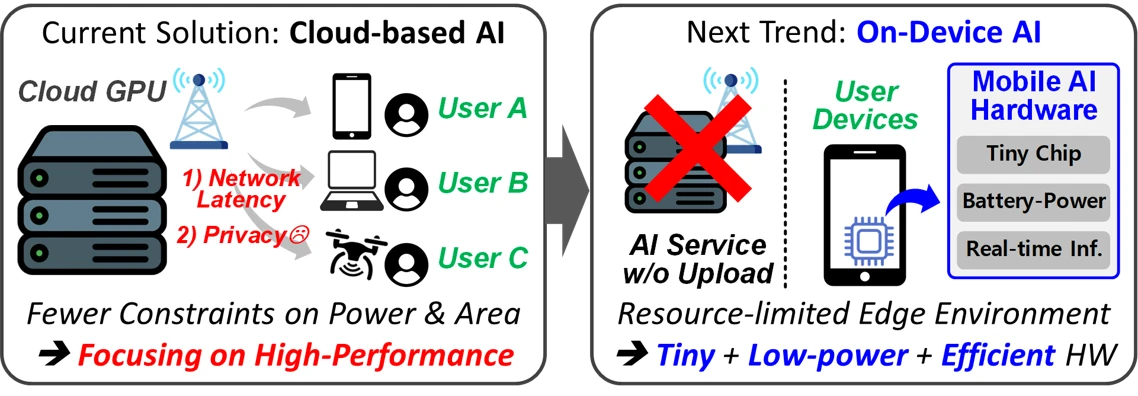
Shift from cloud-based AI to on-device AI that needs tiny, low-power, efficient hardware

Selected publications

ISSCC 2026
  • Circuit
  • LLM
  • Quantization

Revolver: Low-Bit GenAI Accelerator for Distilled-Model and CoT with Phase-Aware-Quantization and Rotation-Based Integer-Scaled Group Quantization

Sangjin Kim, Jungjun Oh, Byeongcheol Kim, Yuseon Choi, Gwangtae Park, Hoi-Jun Yoo

IEEE International Solid-State Circuits Conference, 2026 Invited to JSSC

ISSCC 2025
  • Circuit
  • Diffusion Model
  • Quantization

EdgeDiff: 418.4mJ/inference Multi-modal Few-step Diffusion Model Accelerator with Mixed-Precision and Reordered Group-Quantization

Sangjin Kim, Jungjun Oh, Jeonggyu So, Yuseon Choi, Sangyeob Kim, Dongseok Im, Gwangtae Park, Hoi-Jun Yoo

IEEE International Solid-State Circuits Conference, 2025 Invited to JSSC

ISSCC 2026
  • Circuit
  • LLM
  • Computing-in-Memory

SMoLPU: 122.1μJ/Token Sparse MoE-based Speculative Decoding Language Processing Unit with Adaptive-Offload NPU-CIM Core

Sangwoo Ha, Jingu Lee, Youngjin Moon, Sunjoo Whang, Wooyoung Jo, Gwangtae Park, Sangjin Kim, Soyeon Um, Junha Ryu, Yurim Jo, Hoi-Jun Yoo

IEEE International Solid-State Circuits Conference, 2026

Funded projects

  • Oct. 2026 – presentPrincipal Investigator

    • Algorithm
    • Architecture
    • LLM
    • Quantization

    Democratizing On-Device AI

  • Oct. 2026 – Sep. 2029

    • Circuit
    • Algorithm
    • Computing-in-Memory

    OSCAR: Open-Source AI-Driven PA-DPD with Computing-in-Memory Acceleration for Energy-Efficient 6G FR3 Wideband Transmitters

    6G FR3 광대역 고효율 송신기를 위한 AI 기반 PA-DPD 및 Computing-In-Memory 연산 가속 회로 통합 설계

  • Jul. 2026 – Dec. 2030

    • Circuit
    • Architecture
    • Physical AI

    MOSAIC: Multimodal On-device Sensory AI Computing

    멀티모달 센서-NPU 통합 피지컬 AI 반도체 연구단

  • Mar. 2026 – Dec. 2028

    • Circuit
    • Architecture
    • Processing-in-Memory

    PIM Semiconductor Design Research Center

    PIM 반도체 설계연구센터

  • Mar. 2026 – Feb. 2031Principal Investigator

    • Circuit
    • Architecture
    • Processing-in-Memory
    • LLM

    NPU–SoC and LPDDR–PIM Architecture for On-Device AI Agents and Test-Time Scaling with Multi-Fidelity LLMs

    온디바이스 AI 에이전트와 테스트–타임 스케일링을 위한 멀티 피델리티 LLM 기반 NPU–SoC 및 LPDDR–PIM 아키텍처

Collaborators and supporters

  • National Research Foundation of Korea
  • IITP
  • ETRI
  • Google Research
  • Stanford University
  • KAIST
  • Yonsei University